Exo Labs Ai Clustering
Frontier models.
On hardware you own
Local models in your preferred harness.
Setup a cluster with ease.
Connect your devices via Thunderbolt or USB-C. See your cluster and manage your models from one dashboard.
Make room for bigger models
Exo distributes a model across your devices and optimizes runtime parameters for turnkey simplicity.
Deploy Local AI seamlessly.
Connect through familiar API formats: OpenAI Chat Completions, Responses, Claude Messages, and Ollama.
Llama
A low-level high-performance C/C++ inference engine built on ggml, designed for running LLMs locally with minimal dependencies. It directly handles tensor operations, quantization support and execution. Acts as the foundation layer for many other tools.
Ollama
Ollama is an open-source tool that allows you to run large language models (LLMs) directly on your local machine. This makes it ideal for AI developers, researchers, and businesses prioritizing data control and privacy.
By running models locally, you maintain full data ownership and avoid the potential security risks associated with cloud storage. Offline AI tools like Ollama also help reduce latency and reliance on external servers, making them faster and more reliable.
This article will explore Ollama’s key features, supported models, and practical use cases. By the end, you’ll be able to determine if this LLM tool suits your AI-based projects and needs.
A higher-level local LLM runtime that wraps llama.cpp and related backends into a package system. It adds model lifecycle management, a runtime daemon, API layer and developer tooling on top of the underlying inference engine.
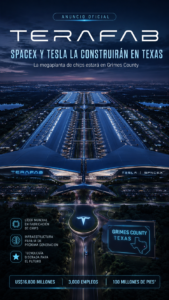
TeraFab – Terafying ?
Terafab is Elon Musk’s proposed attempt to build a semiconductor manufacturing system on a scale intended to serve Tesla, SpaceX and xAI. It is not simply another Tesla factory. The project aims to combine chip design, advanced logic fabrication, memory production, photomasks, packaging and testing within a vertically integrated operation capable of supporting autonomous vehicles, humanoid robots, large AI models and, eventually, computing infrastructure in space